Judging
Judge agents can automatically review a single task result or compare multiple variants to help you identify the best solution. Judges analyze code quality, correctness, and completeness—providing objective feedback that saves you time reviewing variants.
What Are Judge Tasks?
A judge task is a special task that evaluates other tasks in a group. Unlike regular tasks that modify your code, judges:
- Run after primary tasks complete
- Have read-only access to primary task results
- Analyze code quality, correctness, and completeness
- Produce evaluation notes and scoring
- Do not modify your repositories
Judge tasks appear in the task group alongside other variants.
How Judges Evaluate
When a judge task runs, it:
- Reads all primary task results—patches, summaries, exit codes, logs
- Analyzes the code changes each agent made
- Reviews test results and error messages
- Evaluates each variant on multiple dimensions
- Generates a detailed report with scores and recommendations
Evaluation Dimensions
Judges score variants on:
- Correctness: Does the code solve the problem? Are edge cases handled? Do tests pass?
- Code quality: Is it readable, maintainable, and following good patterns?
- Completeness: Are all requirements addressed? Is anything missing?
- Performance: Is the implementation efficient? (when applicable)
Each dimension receives a score, and judges provide detailed notes explaining their reasoning.
Judges may use or add other dimensions based on the task context.
Which code the judge reviews
Each variant has its own checkout, with its patch applied to the recorded base commit for the turn under review. A moving branch such as main no longer changes that base while a judge is waiting to start. Variants launched from the same branch can still have different base commits; they are reviewed in separate checkouts.
The current patch's recorded base takes precedence, including after Pull Latest Changes, MCP pulls, or refreshes outside a new turn. Matching checkpoints provide the result tree and identify their base through the checkpoint's parent. Stale turn records do not move a review back to the pre-pull base, even when patch bytes remain unchanged. New sync snapshots also retain pending-merge information. Legacy tasks with recorded base metadata remain reviewable after their source container is stopped or removed. For results without any base record, the prompt explicitly identifies a launch-branch-tip fallback; an omitted branch uses the launcher's main default. Forced branch selection still applies.
Verified checkpoints restore binary additions and modifications as well as text changes. Separate review artifacts include binary payloads even when no checkpoint is available; the displayed patch stays compact so large assets do not hide text changes. Capture and preparation preserve the original bytes of non-UTF-8 text files as well. For shallow clones, base-sync preparation can fetch bounded missing ancestry before reporting an incomplete resolution view. Source access is time-limited and transfers only objects not already represented by its recorded remote refs; a remote base does not require a full copy of repository history.
The judge's output includes review-inputs.json (captured inputs) and review-checkouts.json (the commits, paths, and preparation results actually used). Patches are applied before the judge starts evaluating. A preparation failure marks the judge failed and releases its execution slot instead of allowing a review of code without the variant's work. The judge runs searches and tests in the prepared checkouts; repository copies used to initialize the container are not review results.
Ordinary reviews without project landing context do not require an integration section. Base-sync instructions appear only when a pending merge is recorded.
For an orchestration child with a recorded project branch, the judge also captures that branch's tip when preparing its checkouts. If it differs from the child's base or launch branch, the judge gets an untouched landing checkout and a separate checkout with the child's patch applied for integration checks. Repositories without a patch share their landing and integration checkout, retaining current code for combined tests without a duplicate copy. The report separates Own changes from Integration with the current landing branch, and marks integration-only findings [integration-only]. An unavailable landing branch or an integration conflict is reported explicitly. The existing verdict rules still apply; this does not add a new automatic integration gate.
For a verified pending base-sync merge, the judge reviews conflict resolutions against Git's automatic merge and checks combined test evidence. Incoming base changes are not treated as the child's work. Defects verified to already exist in the incoming base are labeled [base-existing informational] and do not fail the verdict. Retained task-test output is copied into variant-tests/; agent-run tests remain available in summaries and visible responses. Missing, unfinished, or stale test evidence is not a pass.
Each review-loop round captures that round's inputs again. The loop's Pull latest changes setting still controls pulling in the child before its feedback turn; pinning does not introduce another pull into the child.
Automatic Judging
You can configure automatic reviews for future task submissions, including tasks you stage for later execution and tasks launched from objectives.
Configuring Auto-Judge
Open Auto-review tasks… in the task launcher's options menu. In Auto-review Settings:
- Select which agents should serve as reviewers. Select no agents to turn automatic reviews off.
- Set Automatically review to one of these minimums:
- 2 or more tasks with changes — the default, preserving comparison-only behavior for existing settings.
- 1 or more tasks with changes — includes single-task reviews and groups where only one variant produces eligible changes.
- Optionally, with the minimum set to one, tick Keep reviewing until Pass and set max rounds and the feedback priority (send). When the automatic review covers a single task, it then runs as an auto-review loop; see Keep Reviewing Until Pass. Comparisons of several tasks still run once.
- Click Save. The preference is saved in your browser and copied into groups created for future submissions. It does not change existing groups.
Multiple reviewers provide independent evaluations, reducing bias and increasing confidence in the results.
When Auto-Judge Launches
Judge tasks launch automatically when:
- All primary tasks have finished (completed, failed, or interrupted).
- The selected minimum number of primary tasks completed successfully and made file changes. Failed tasks and completed tasks without changes do not count toward the minimum.
- None of the primary tasks has follow-up history; this automatic launch applies to their initial execution.
- At least one configured reviewer has not already been launched for the group.
With exactly one eligible result, the judge uses review mode. With two or more, it compares the eligible variants. Even when the minimum is one, reviewers wait for every primary task to finish.
Moving, regrouping, or reordering existing tasks does not itself trigger automatic reviews. For example, adding an existing result to a group before resubmitting variants does not consume the reviewers before the new variants finish.
If conditions aren't met, automatic judging is skipped—but you can launch judges manually.
Manual Judge Launch
You can launch judge tasks at any time:
- Open the task group
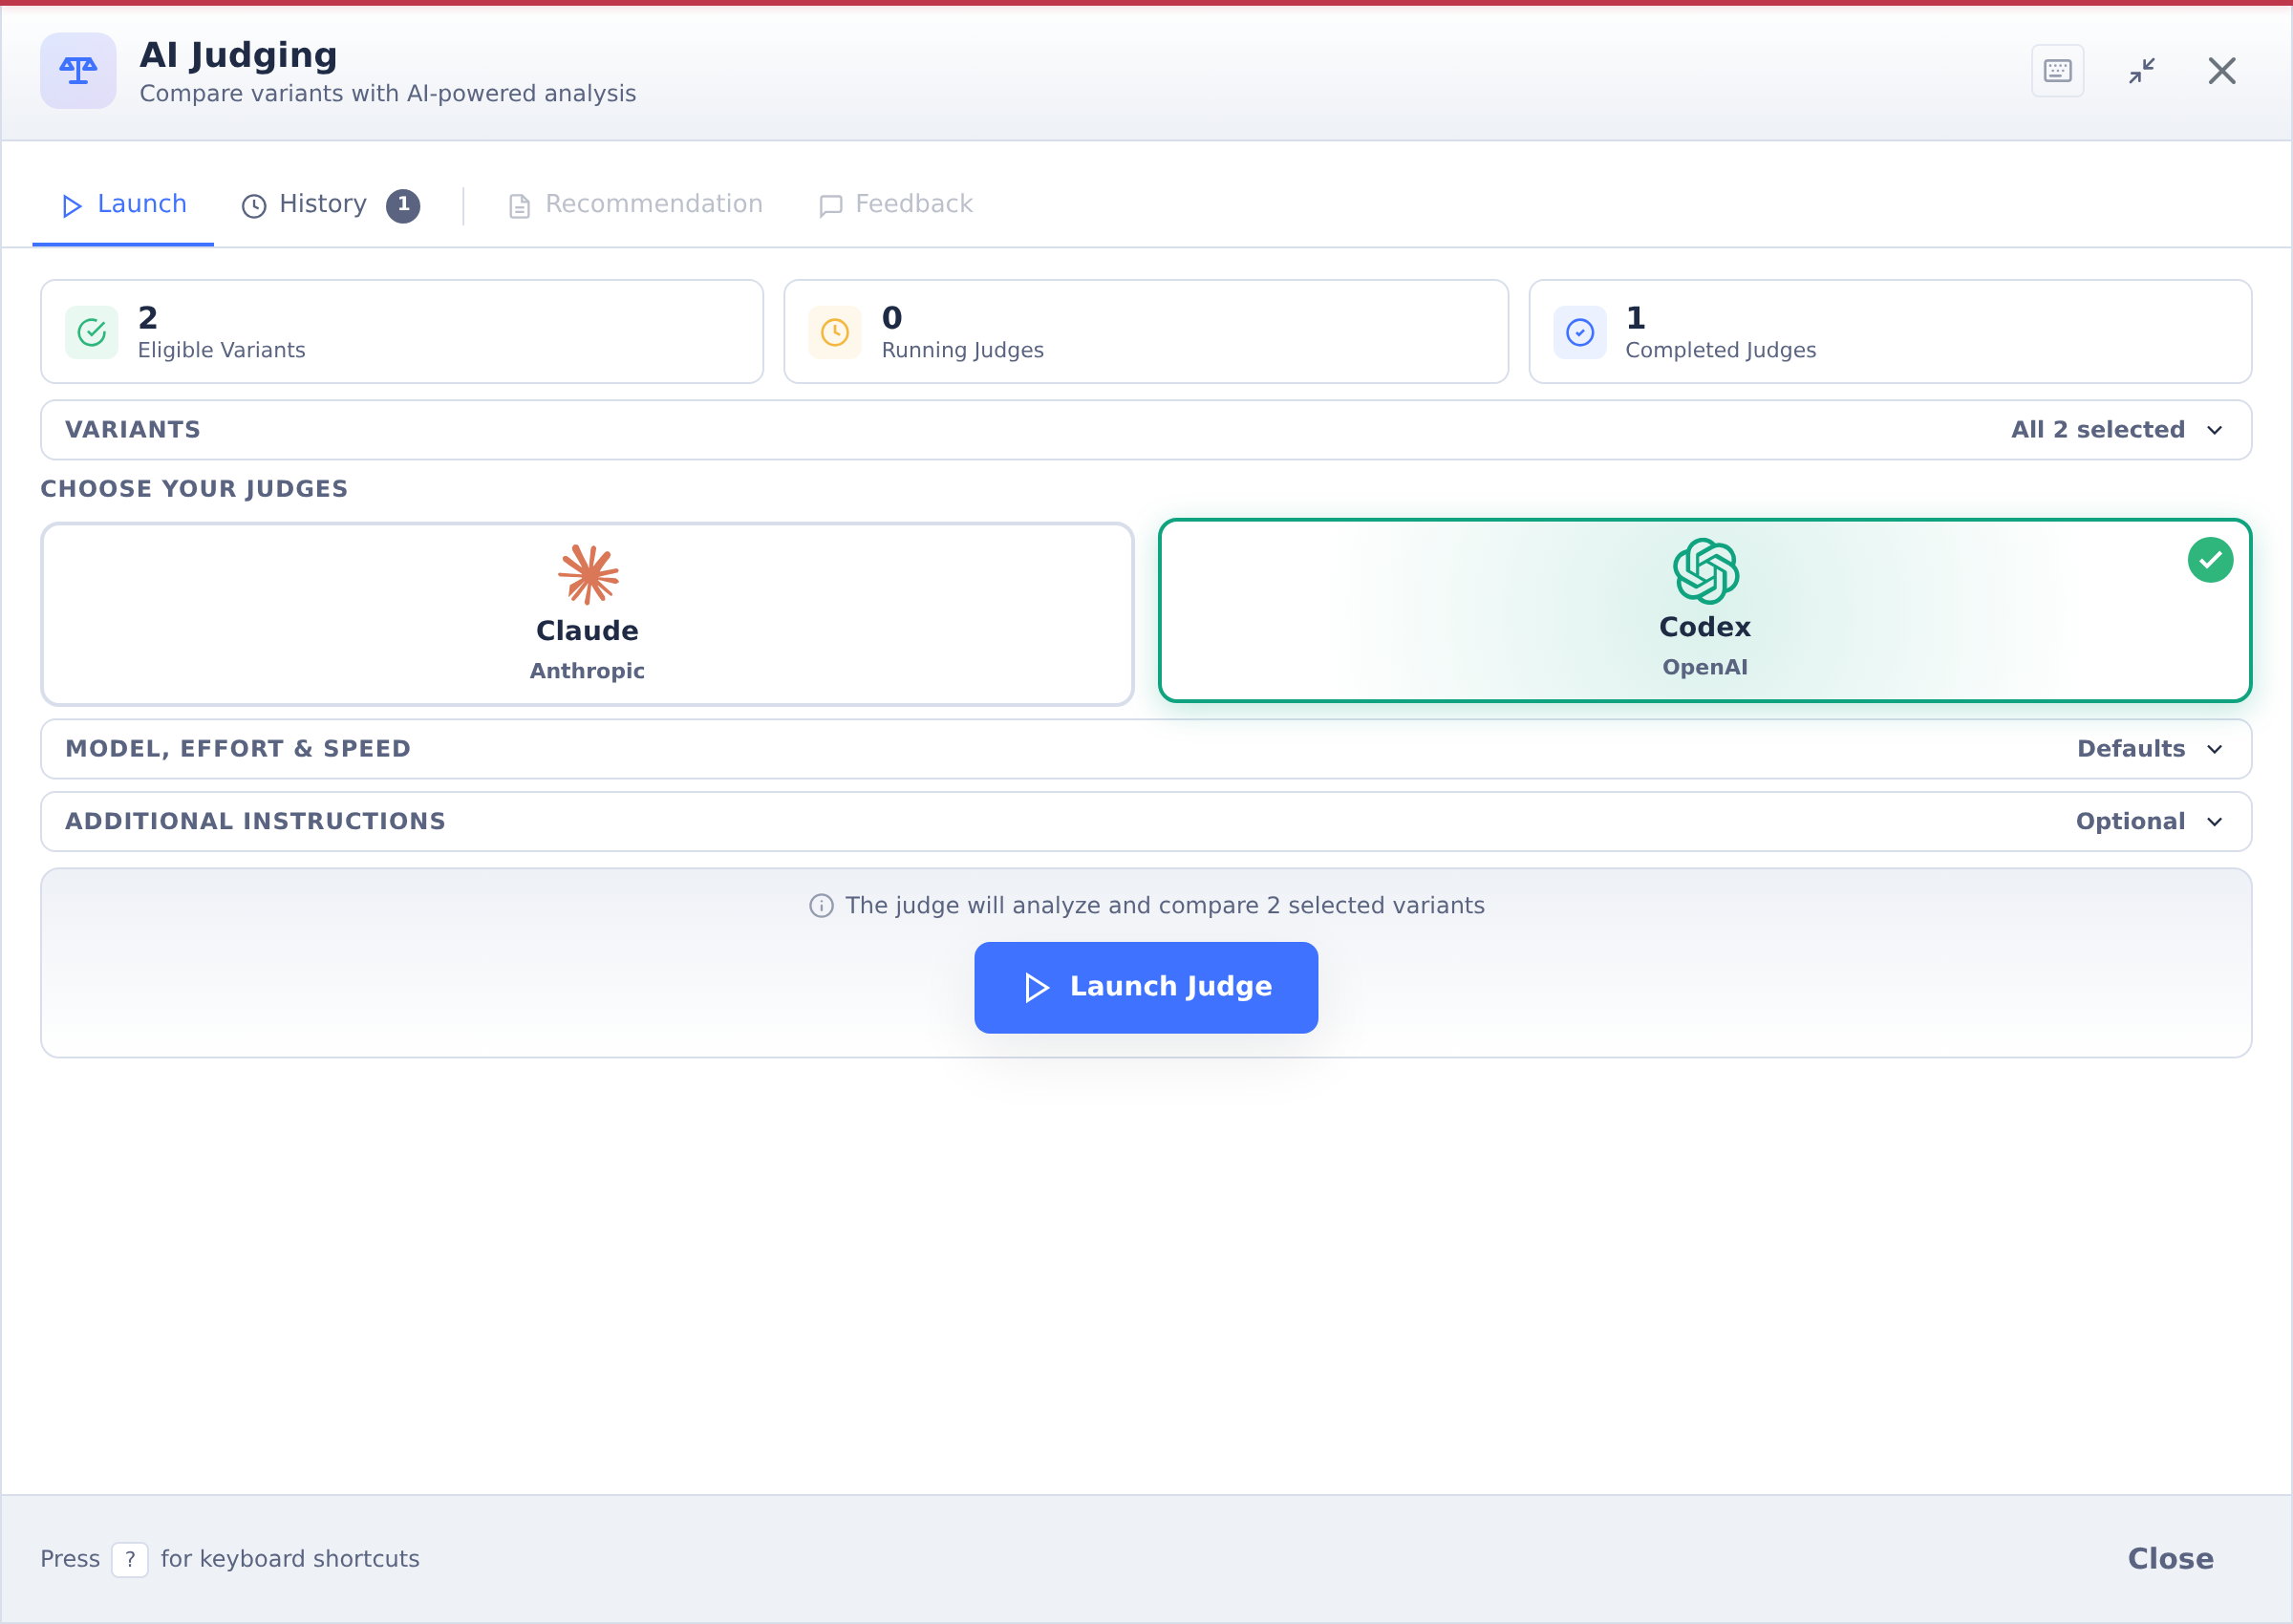
- Click the Judge button
- Select which variants to review and which agents to use as judges
- Click Launch Judge (or Launch Review for one variant) to create and queue the judge tasks
This is useful when auto-judge conditions weren't met, or when you want additional evaluation after making changes.
A judge holds copies of each variant's responses and changes. When any variant it evaluates is private, the judge task is private too: only its creator and people with tasks:view_any can open it. A judge also becomes private when one of its variants is made private later, and can't be shared again while that variant is private. If you can open a judge but not every variant it evaluated, it shows Review content withheld instead of its recommendation and output, and you can't follow it up, fork, export or judge it. If you're given access to those variants again, the content shows the next time the page refreshes. On the dashboard and in task lists it appears as "Review" or "Judgment" (a judge is named after the first variant it evaluated) with its status, but no preview or activity detail, and its completion notification doesn't quote it. A judge of a judge, or a fork of one, follows the same rule.
Review Mode
Judging compares variants against each other, so it needs at least two. When you select a single variant instead, the judge switches to review mode and evaluates that one solution on its own merits.
The difference is what comes back. A comparison judge names a winner; a review judge returns a verdict:
- Pass: the solution is correct and acceptable
- Needs Improvement: functional, but has issues
- Fail: incorrect or fundamentally flawed
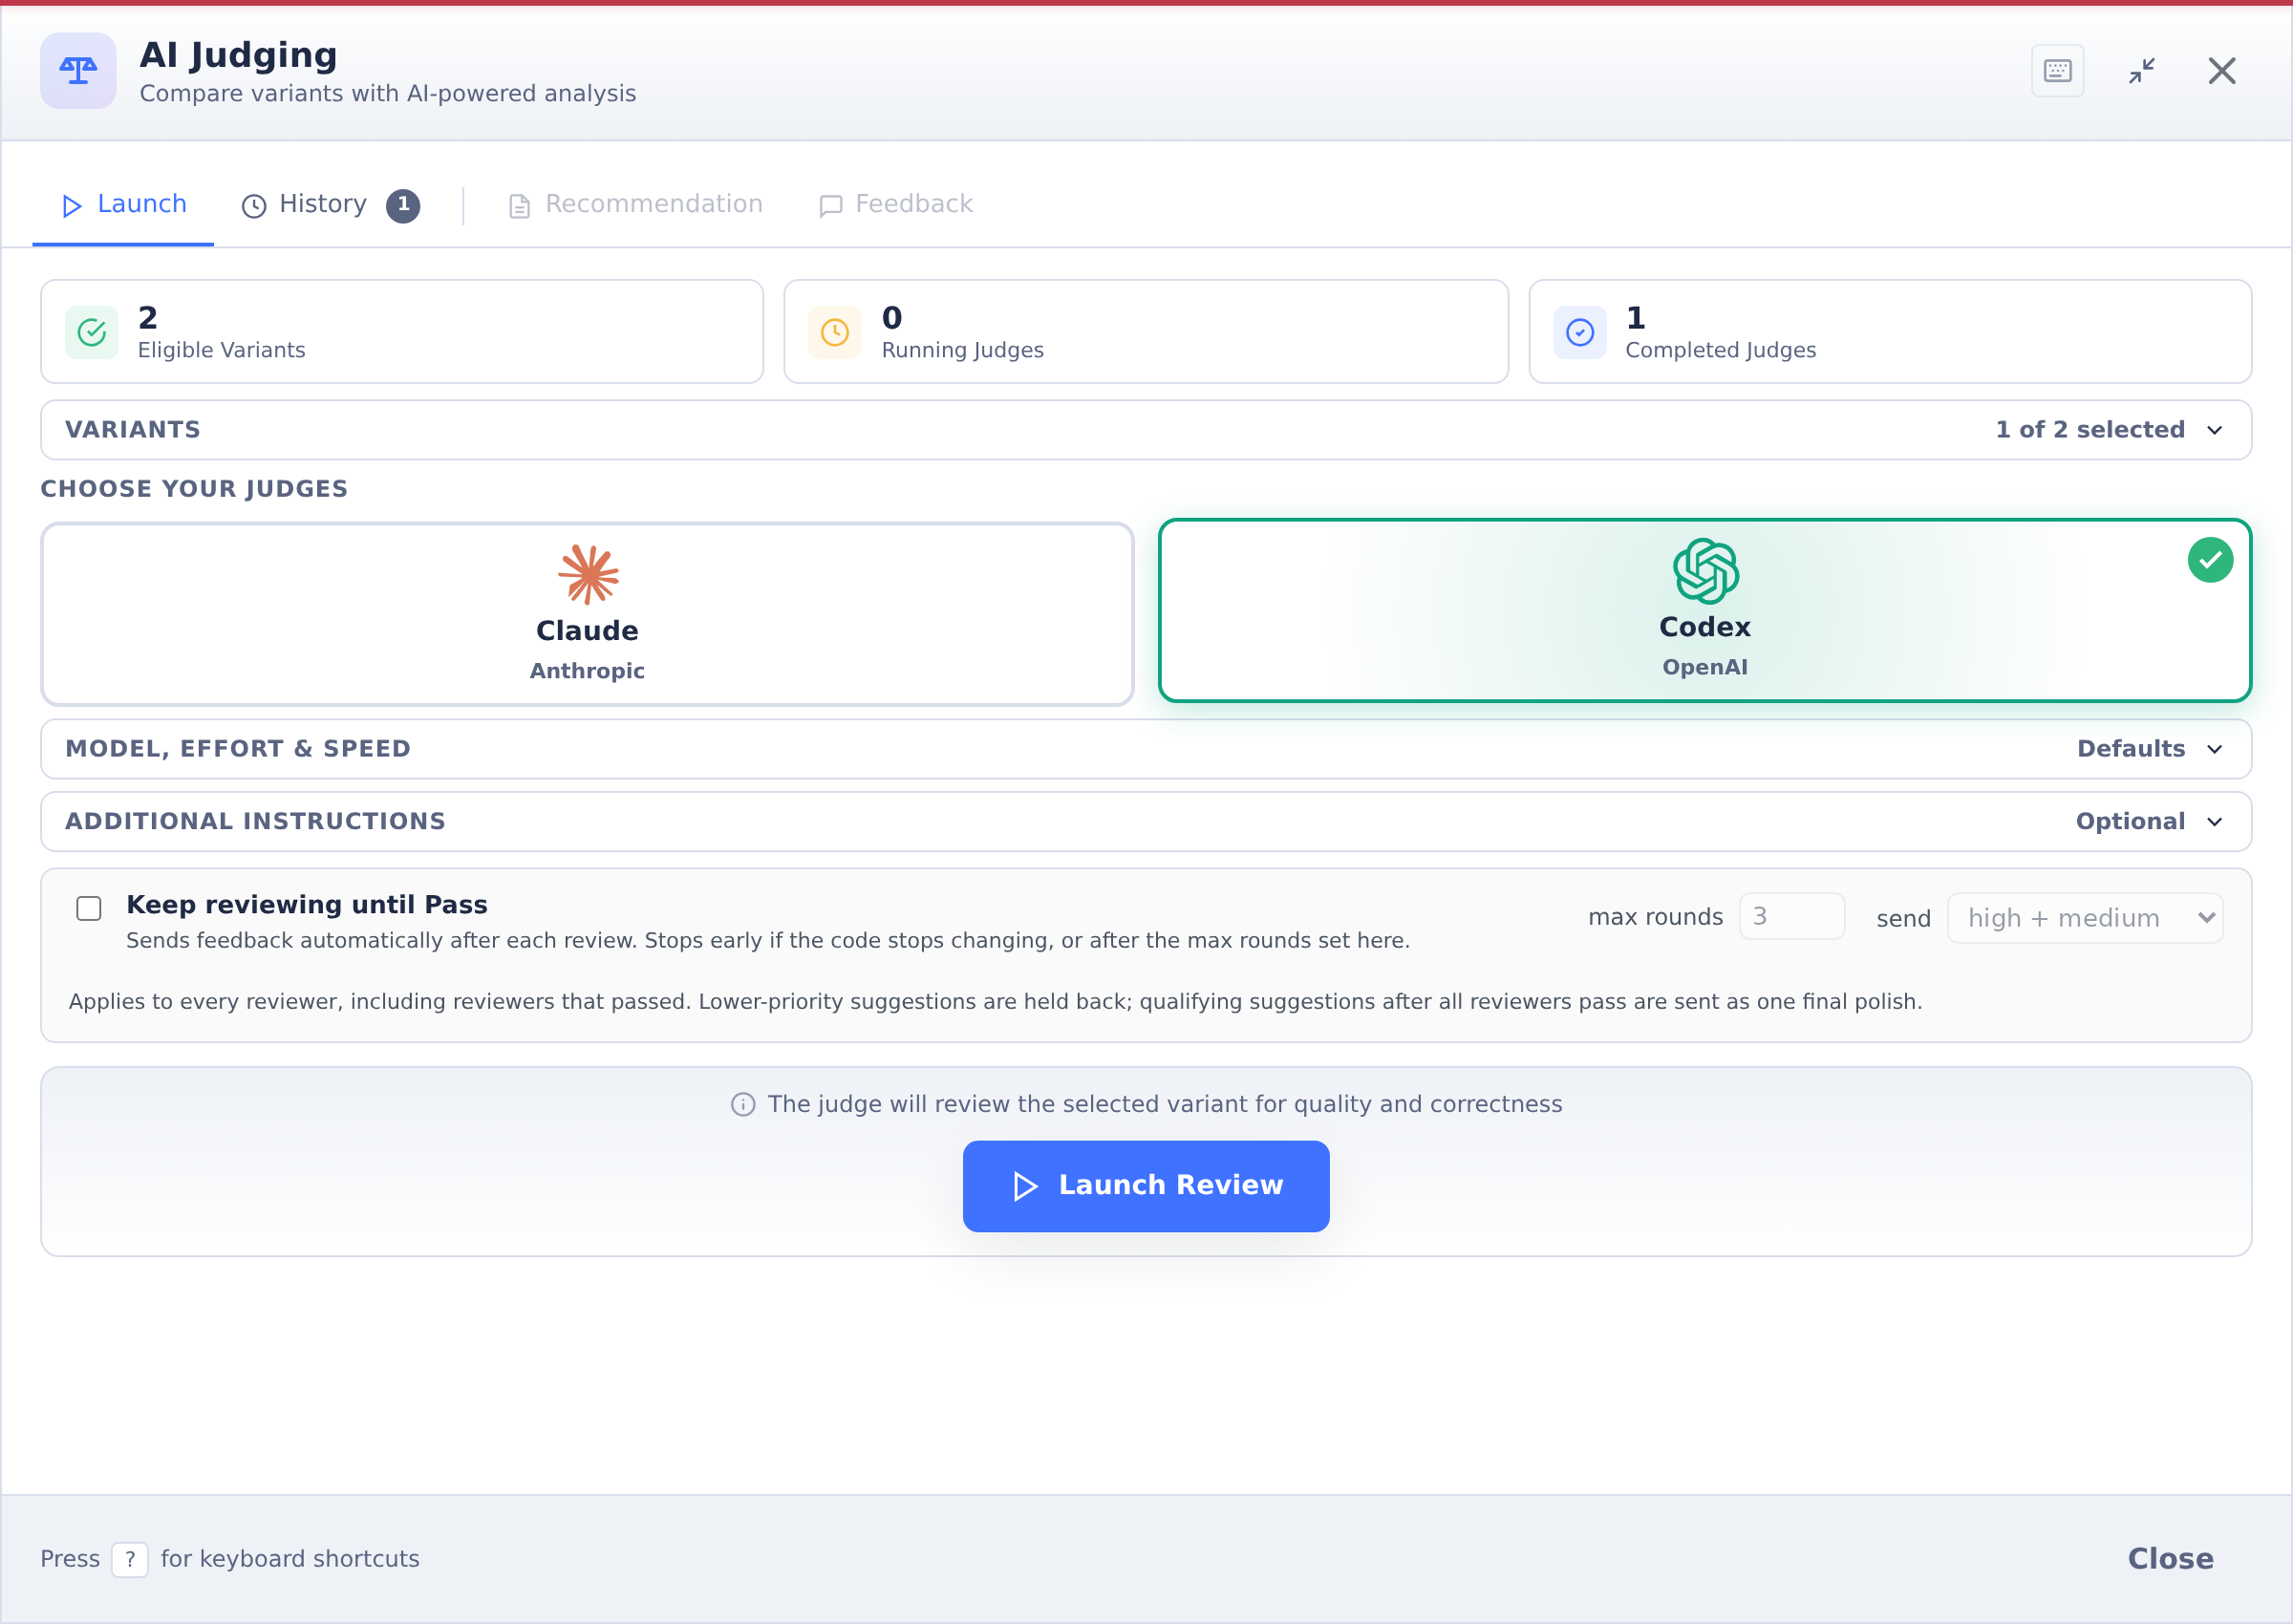
To launch one, open the Judge panel, select exactly one variant, and choose your judges. The launch button changes to Launch Review. Verdicts appear on the judgment cards in the History tab.
Reviews can also launch automatically: choose 1 or more tasks with changes in Auto-review Settings before submitting the task. If exactly one result meets the eligibility rules above, the automatic judge uses the same review mode and returns a verdict. The default minimum of two continues to produce comparisons.
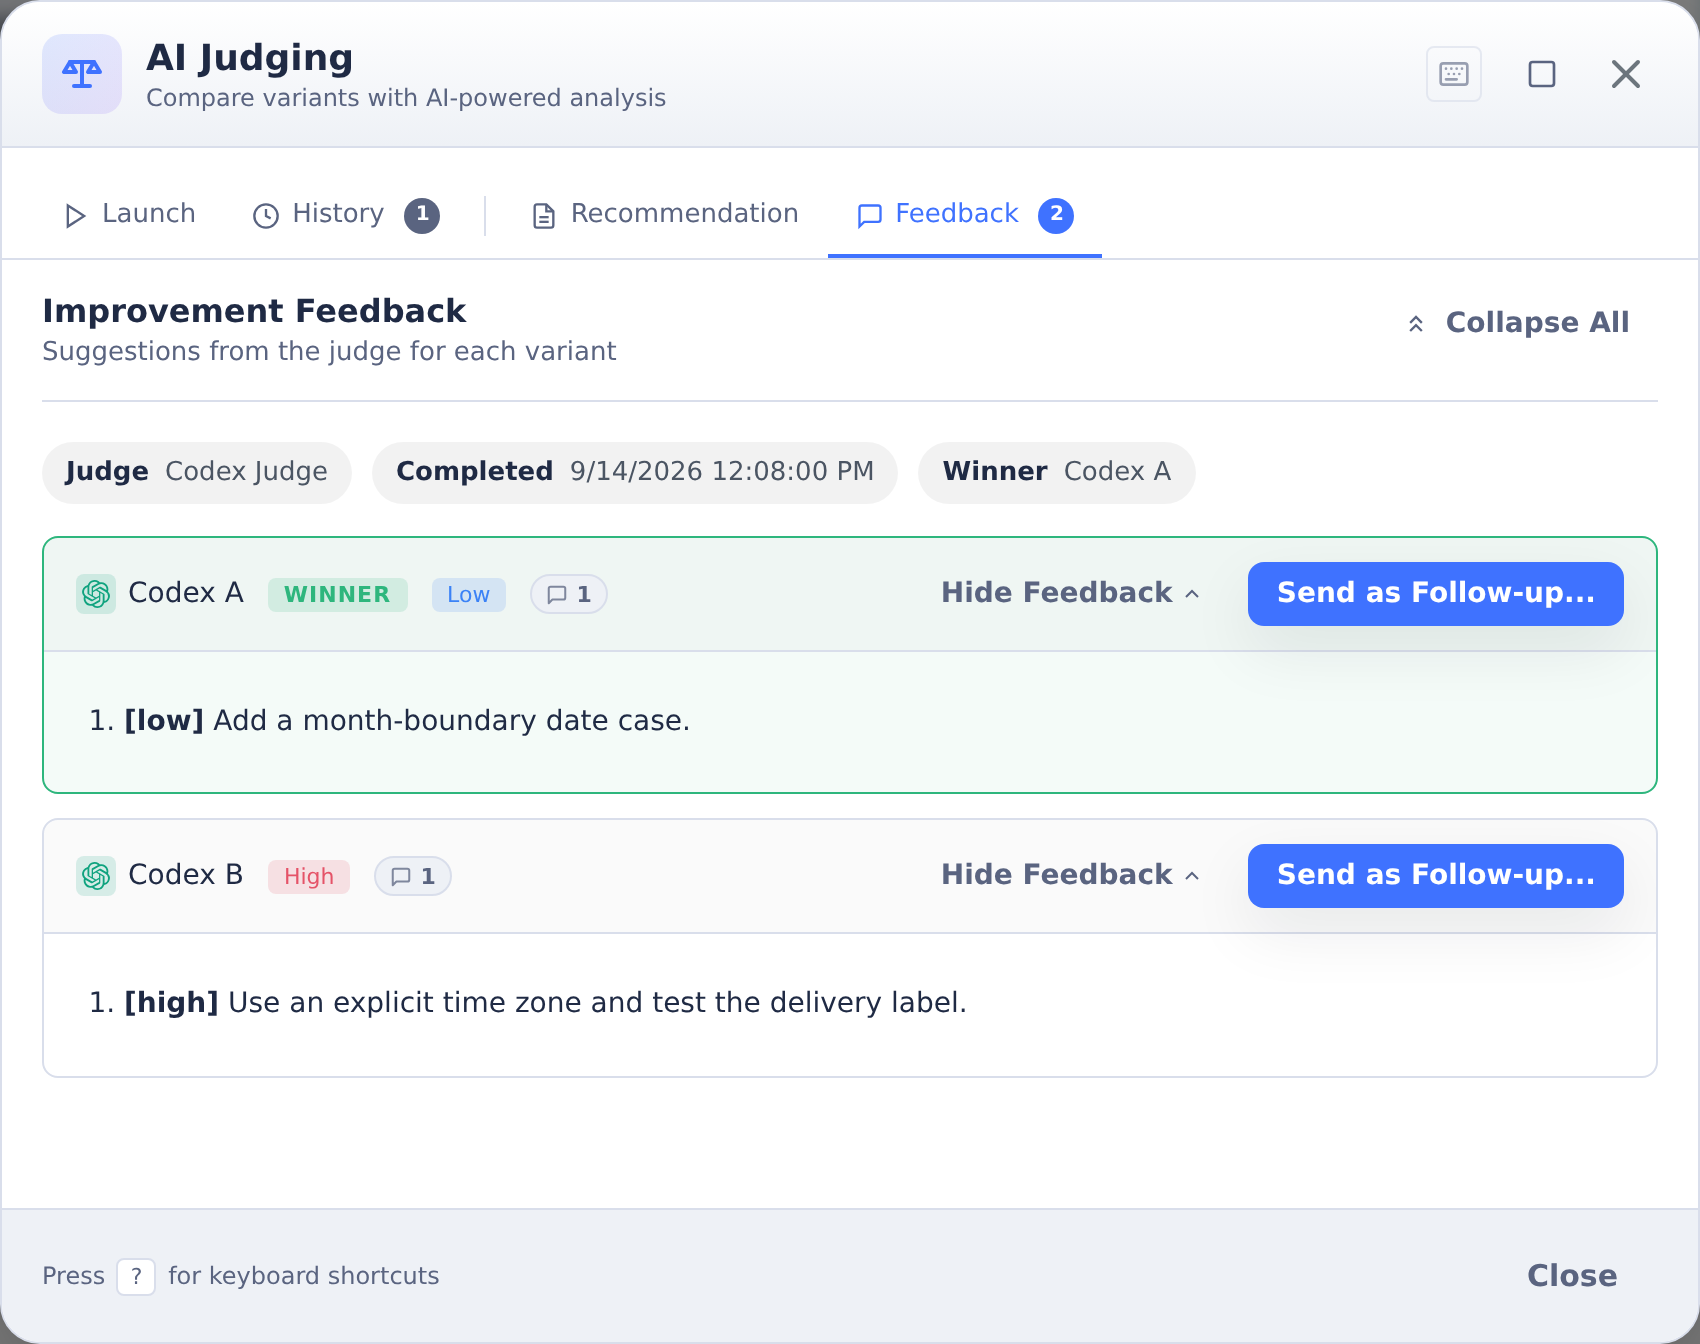
A review judge still fills in improvement feedback, even when the verdict is Pass. Treat the verdict as the decision and the feedback as suggestions.
Judge Consensus
When multiple judges evaluate the same variants:
- Each judge scores independently
- Results can be compared side-by-side
- Consensus emerges when judges agree on the best variant
- Disagreements highlight areas worth closer review
If two out of three judges recommend the same variant, that's a strong signal. If judges disagree significantly, you may want to review their reasoning before deciding.
Using Judge Feedback
Judge feedback isn't just for picking a winner—it helps you improve the code.
Select a completed judgment in History, then open Feedback. Expand a variant's feedback to review its suggestions. Use Send as Follow-up… to prepare instructions for that variant. Ask CoderFlow can open the AI Judging dialog on the right tab and point at a variant's Send as Follow-up…, an auto-review's Stop or Continue, or Cancel request; you send, stop or cancel yourself.
A follow-up stays in the task's history, readable by everyone who can view the task, and a comparison judge's feedback can quote any variant it compared. So CoderFlow sends feedback into a task on its own (the auto-review loop, or the API's judge-feedback follow-up) only when every variant the judge evaluated is in the task's environment and, for a shared task, shared; for a private task, one its owner can open. Send as Follow-up… sends the text you edited as your own follow-up, so check it before sending a comparison's feedback to a task other people can view.
Common Issues Judges Identify
- Test failures: Some tests aren't passing
- Edge cases: Boundary conditions not handled
- Error handling: Missing validation or exception handling
- Code style: Inconsistent naming or formatting
- Incomplete implementation: Features not fully implemented
Feedback Loops
After reviewing judge feedback:
- Identify specific issues mentioned in the evaluation
- Send follow-up instructions to the winning variant addressing those issues
- The agent resumes and implements improvements
- Optionally re-run judges to verify the improvements
This creates a refinement cycle where judges catch issues that agents then fix. See Providing Feedback for how to send judge feedback as a follow-up.
Keep Reviewing Until Pass
In review mode, CoderFlow can run that cycle for you instead of you repeating it by hand.
Tick Keep reviewing until Pass in the Judge panel before launching, and set a round limit. After each review, the feedback is sent to the variant automatically, the variant addresses it, and the same judges re-evaluate. That is one round.
To loop automatic reviews too, tick the same option in Auto-review Settings (see Configuring Auto-Judge). When the submitted work finishes with exactly one task with changes, its reviewers start the loop, which then behaves as described here. The follow-ups are sent in the name of the person who submitted the task, so that person needs permission to change tasks in the environment. Without it, the reviews still run once, and the History tab says why the loop did not start.
The loop finishes under these conditions:
- Every reviewer passes. Each reviewer must return a usable verdict. A failed, interrupted, or unreadable review is re-run once in the same round with the same agent and settings; another missing verdict stops the loop with
judges_failed. - The rounds run out. You set the limit when you launch, up to ten. You can then continue the loop; see Continuing After the Rounds Run Out.
- The variant stopped changing code. If a turn produces no changes, the agent has effectively declined the feedback, and another round would only repeat itself.
- A reviewer's feedback can't go to the variant. Feedback quotes the work a reviewer evaluated, so it is sent only when everyone who can view the variant can open all of that work (see Using Judge Feedback). Otherwise the loop stops with
feedback_withheldinstead of sending it.
Turns the loop did not send are not rounds. A follow-up someone sends the variant while a round is under review, including a message from the task that created it, runs as an ordinary turn, and the loop carries on. If the round's verdicts arrive while that turn runs, the loop's feedback waits and is sent when the turn ends. The same applies when such a turn starts just as the feedback is being sent. If that turn never gets going (its launch failed), the loop tries again for about two minutes, then stops with follow_up_failed.
Minimum feedback priority applies to every reviewer, including reviewers that passed (default: medium). Each feedback follow-up keeps the reviewer headings and verdicts. When every reviewer passes, remaining suggestions at or above the threshold are sent as one final polish follow-up, including on the last allowed round. No further review launches. The loop remains running until that turn ends, then reports passed_after_polish, polish_failed, or polish_interrupted. With no qualifying suggestions it stops immediately with passed.
The History tab shows the current round while the loop runs, with a Stop button, and the reason it stopped once it finishes. Group completion notifications are held until then, so you are notified once at the end rather than once per round.
With more than one judge, a round waits for all of them, then merges their feedback into a single follow-up so the variant addresses everything in one turn. A missing verdict must be retried successfully before the round can proceed.
The round limit bounds review/fix cycles. Missing-verdict retries and the single final polish turn can add work beyond those cycles. Three rounds is a reasonable default.
The loop is offered in review mode only. Comparison judging returns a winner rather than a verdict, so there is no pass condition to stop on.
Continuing After the Rounds Run Out
If the last allowed round still asks for changes, the loop stops without sending that round's feedback, because no review would check the fix. You don't need to send it by hand and start a new review. The History tab shows Continue with a more rounds count next to the stop reason. The count starts at the number of rounds you allowed last time, and you can add up to ten at a time.
Continue sends the held-back feedback and picks up from the same round, with the same reviewers, settings and feedback priority. The banner then counts toward the new total, for example round 4 of 6. The loop finishes under the same conditions as before. If it runs out again, you can continue again. Follow-ups after a continue are sent in your name. If the task's container was stopped while idle, Continue starts it first; if it can't be started, nothing changes and Continue stays available.
Continue appears only on a loop that ran out of rounds, and only until you launch another review. CoderFlow refuses it while the task is working on a turn, while a rewind is waiting for the task's next instruction, and if the task received any follow-up after the last round's review started. In each case, the feedback could describe code that has since changed. Send feedback by hand or launch a new review instead. A loop also stops without sending anything if a rewind is prepared on the task before its feedback is delivered.
Judges Don't Approve
Important: Judge tasks provide feedback and recommendations only. They do not:
- Automatically approve changes
- Commit or push code
- Mark tasks as winners
You make the final decision on winner selection and approval. Judges inform your decision—they don't make it for you.